Skip to content

Redwood City, CA
--:--:--

37.4852° N
122.2364° W

Member of Technical Staff — Thinking Machines Lab

PawanBhandarkar

I build the instruments that let researchers see inside frontier models.

Scroll to explore
(01)Thesis

Frontier models are only as good as what their researchers can see. I build the instruments that make training legible, for the people running the experiments and, increasingly, for their agents.

Years shipping production software
6+
Frontier AI labs
2
Monthly users reached by real-time systems I worked on
7.5M
(02)Now — Thinking Machines Lab

Building the lab’s research acceleration platform.

I created and lead the platform researchers use to inspect training runs, RL rollouts, datasets and evals, and built it end to end, from the database schema to the last pixel. It’s the second one I’ve built; the first was Nebula at xAI.

  1. 01Watch the run

    Reward, loss and eval curves, checkpoint leaderboards across benchmarks, GPU-hour cost accounting, alerts, and rollouts streamed live from running jobs.

  2. 02Read the data

    Rollout and training-data viewers with rendered token views, regex search, dataset diffs, data-mix accounting, and lineage from dataset to checkpoint.

  3. 03Find the patterns

    Unsupervised conversation clustering, from LLM facet extraction through embeddings to hierarchical clusters, surfaces themes and failure modes at scale.

  4. 04Let agents in

    A typed Python SDK, anchored annotations and a citation graph let AI agents read research artifacts and cite their evidence.

Research platform
Illustrative

reward / mean

0.87

liveGPU·h 1,284
0step 10k20k
▲ eval / math — new best
reward (ema) eval
regex /tool_call.*timeout/128 matches
#7270+0.14
#507c+0.66
#326b−0.01
#9177−0.02
#3271+0.68
#e820−0.37
facets → embeddings → clusters12,480 conversations
tool-call loopsformat driftrefusalsarithmetic slips
Why did the math eval regress after step 14k?

agent

The drop concentrates in one cluster: arithmetic slips inside long tool-call chains, starting with the data mix that landed at 14k. These rollouts show it most clearly:

↳ rollout #a3f1↳ rollout #77c0↳ eval · math @14k↳ dataset diff · mix v12
(03)Previously — xAI

The tools behind Grok.

Before Thinking Machines, I built this kind of instrument for the first time at xAI, along with the platform that produced Grok’s human data and the agents researchers worked alongside.

01Model debugging & RL observability

Nebula

xAI's tier-0 platform for end-to-end model development and debugging, and the first research platform I built.

  • File, trace and production-data viewers, benchmark queuing and automation, and model deployment automation.
  • The RL Data App: high-performance aggregation and analytics for RL training and eval metrics, used in every RL workflow at xAI.
  • Dashboards and trace viewers that cut researchers' manual review of agent behavior from hours to seconds.

7,000+

engineering hours a week spent in Nebula

trace · rollout #8812 · 3 turns · 11 spans

0s12s24s36s
episode
turn 1
model.generate
tool · python
turn 2
model.generate
tool · search
turn 3
model.generate
grader
reward
model.generate · 4,812 tokens · 6.1sgrader 0.82
Illustrative

02Human data platform

Starfleet

I owned and scaled xAI's human-data platform for human evals and the high-quality post-training data behind Grok 3 and Grok 4.

  • Multi-model arenas, QA pipelines and auto-graders across personality, multilingual audio and process-supervision projects.
  • Real-time analytics, performance management and HRIS-style operations for the teams producing the data.
  • Infrastructure, Grafana dashboards and alerts that kept it, and every platform here, reliable.

Grok 3 & 4

post-training data collected on Starfleet

arena · task #1047 · personality

Response A

Response B

A ≫ BA > BTieB > AB ≫ A
helpfulness●●●●●
tone●●●●●
accuracy●●●●●
concision●●●●●
QA ✓ 2 of 2 reviewersauto-grader 0.91throughput ▲ 12%
Illustrative

03Tools that work alongside researchers

Agents

Agents and notebooks that let researchers and engineers hand off the analysis and the busywork.

  • Research Agent: a Cursor-style assistant on Nebula that analyzes RL training and eval data through an MCP server of model-debugging tools.
  • Nebula Notebooks, built solo: an in-house Colab with managed Jupyter kernels and custom renderers for agent traces and grader results.
  • Devbots: I led a team of three to ship xAI's remote coding agents, reachable from Slack, the web and PR reviews, each in a sandboxed environment.

Team of 3

I led to ship Devbots

› @run-8812 why did reward collapse at step 3k?

→ rollouts.query(run=8812, steps=2900..3100)

→ cluster(by="failure_mode")

→ notebook.open("reward-debug", cell=12)

devbot opened a PR · fix reward clipping
Illustrative
(04)Experience2020 → now

A training run in five checkpoints.

ckpt 01 / 05Feb 2020 — Apr 2022

Team AIBOD

Software Engineer · Fukuoka, Japan

Shipped full-stack products for clients across Japan, from internal search to payments.

  • Built an information management system serving up to 150,000 users a day with Python, SQL and GraphQL.
  • Led a payment microservice (gRPC, Flask, PostgreSQL), and built and documented 30+ REST APIs with Apiary and Postman.
  • Created an accessible, mobile-first React component library, and set up Jenkins CI/CD automating 100+ weekly builds on AWS.

150K

daily users on one system

  • Python
  • GraphQL
  • React
  • gRPC
  • PostgreSQL
  • AWS
ckpt 02 / 05Jun 2023 — Aug 2023

TuneIn

Software Engineer Intern, Platform · San Francisco, CA

Real-time infrastructure for one of the largest audio platforms on the internet.

  • Enhanced real-time delivery for up to 7.5 million monthly users with WebSocket subscription APIs in a Go GraphQL gateway.
  • Built pipelines processing 2M+ messages a day under 30 ms with ActiveMQ and Redis Streams.
  • Extended the C# (.NET Core) monolith with live-streaming metadata for 120,000+ radio stations, and automated deploys with Terraform and Kubernetes.

7.5M

monthly users reached

  • Go
  • GraphQL
  • WebSockets
  • Redis Streams
  • Kubernetes
  • Terraform
ckpt 03 / 05Jan 2024 — Dec 2024

Converge Lab

Founding Engineer · Sunnyvale, CA

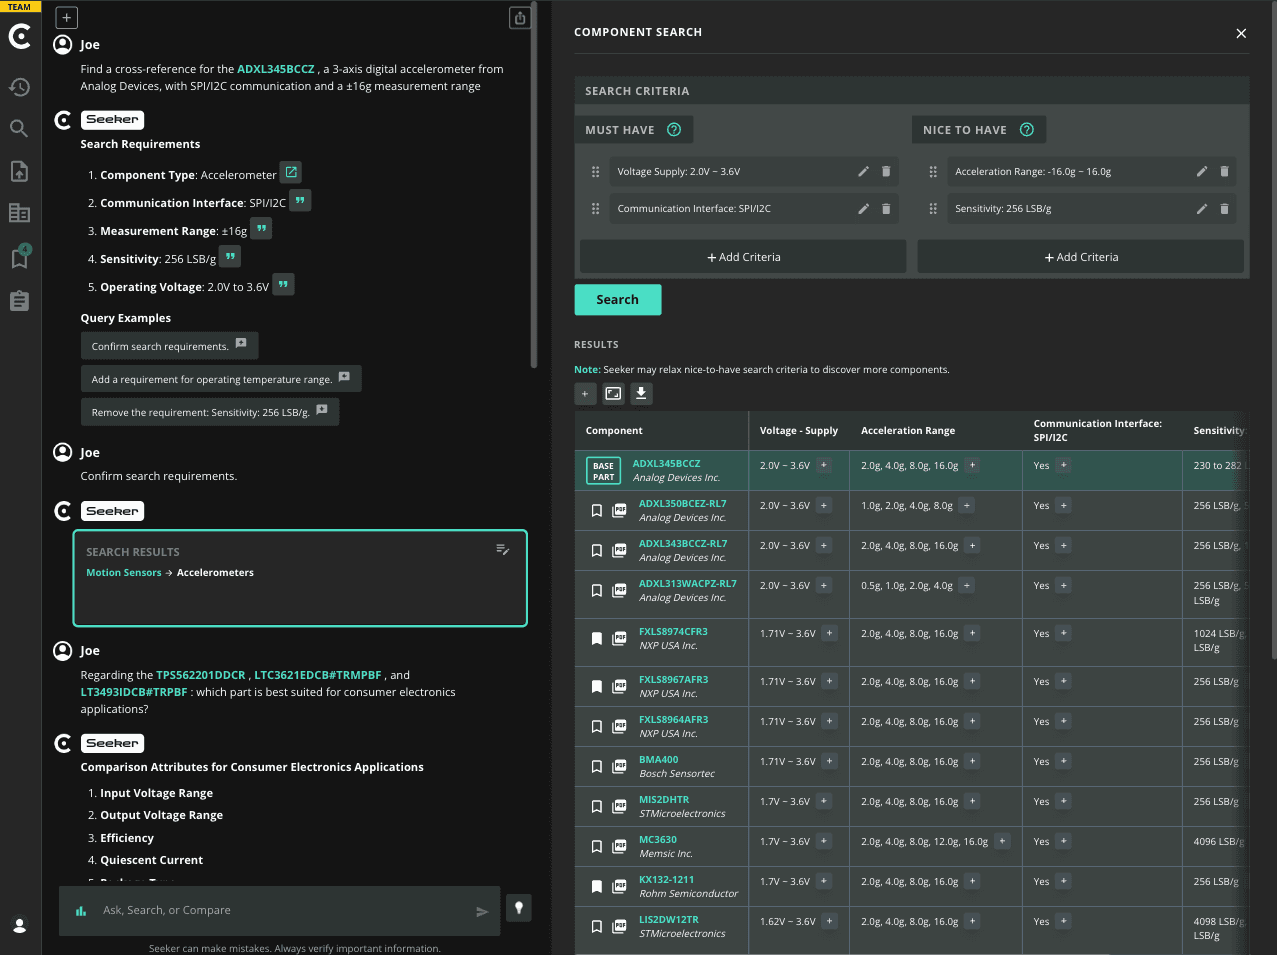
Built and launched an LLM hardware co-designer that helps field application engineers find and compare components.

  • Built the Next.js and TypeScript frontend: generative UI over server-sent events, human-in-the-loop feedback for AI evaluation, and tiered access control.
  • Contributed to a FastAPI RAG backend (Pinecone, Elasticsearch, DynamoDB, LangChain) and Python pipelines that parse PDF datasheets for LLM context.
  • Helped secure a partnership with Nvidia and the first 100 users.

100

first users, plus an Nvidia partnership

  • Next.js
  • TypeScript
  • FastAPI
  • LangChain
  • Pinecone
  • Elasticsearch
ckpt 04 / 05Dec 2024 — Mar 2026

xAI

Member of Technical Staff · Palo Alto, CA

Owned the model-debugging, RL-observability and human-data platforms behind Grok's training.

  • Owned and scaled Starfleet, xAI's human-data platform for human evals and post-training data behind Grok 3 and Grok 4.
  • Built Nebula, the tier-0 model-debugging and RL-observability platform where xAI spent 7,000+ engineering hours a week.
  • Shipped agents for researchers and engineers: the Nebula Research Agent, Nebula Notebooks (solo), and Devbots, which I led a team of three to build.

hrs → sec

researchers' manual review of model behavior

  • TypeScript
  • React
  • Python
  • MCP
  • Notebooks
ckpt 05 / 05Apr 2026 — Now

Thinking Machines Lab

Member of Technical Staff · San Francisco, CA

Created and lead the lab's research acceleration platform for inspecting training runs, RL rollouts, datasets and evals.

  • Built RL run dashboards and eval leaderboards: reward, loss and eval curves, checkpoint comparisons across benchmarks, cost accounting, alerts and live rollout streaming.
  • Shipped training-data tooling: dataset viewers with rendered token views, large-scale regex search, dataset diffs and lineage across datasets, jobs and checkpoints.
  • Built an unsupervised conversation-clustering pipeline that surfaces themes and failure modes, and opened research artifacts to AI agents.

Current checkpoint · still training

  • React
  • TypeScript
  • FastAPI
  • ClickHouse
  • Kafka
  • BigQuery
(05)About

Fig. 1 — the author

Engineer by trade, designer by habit.

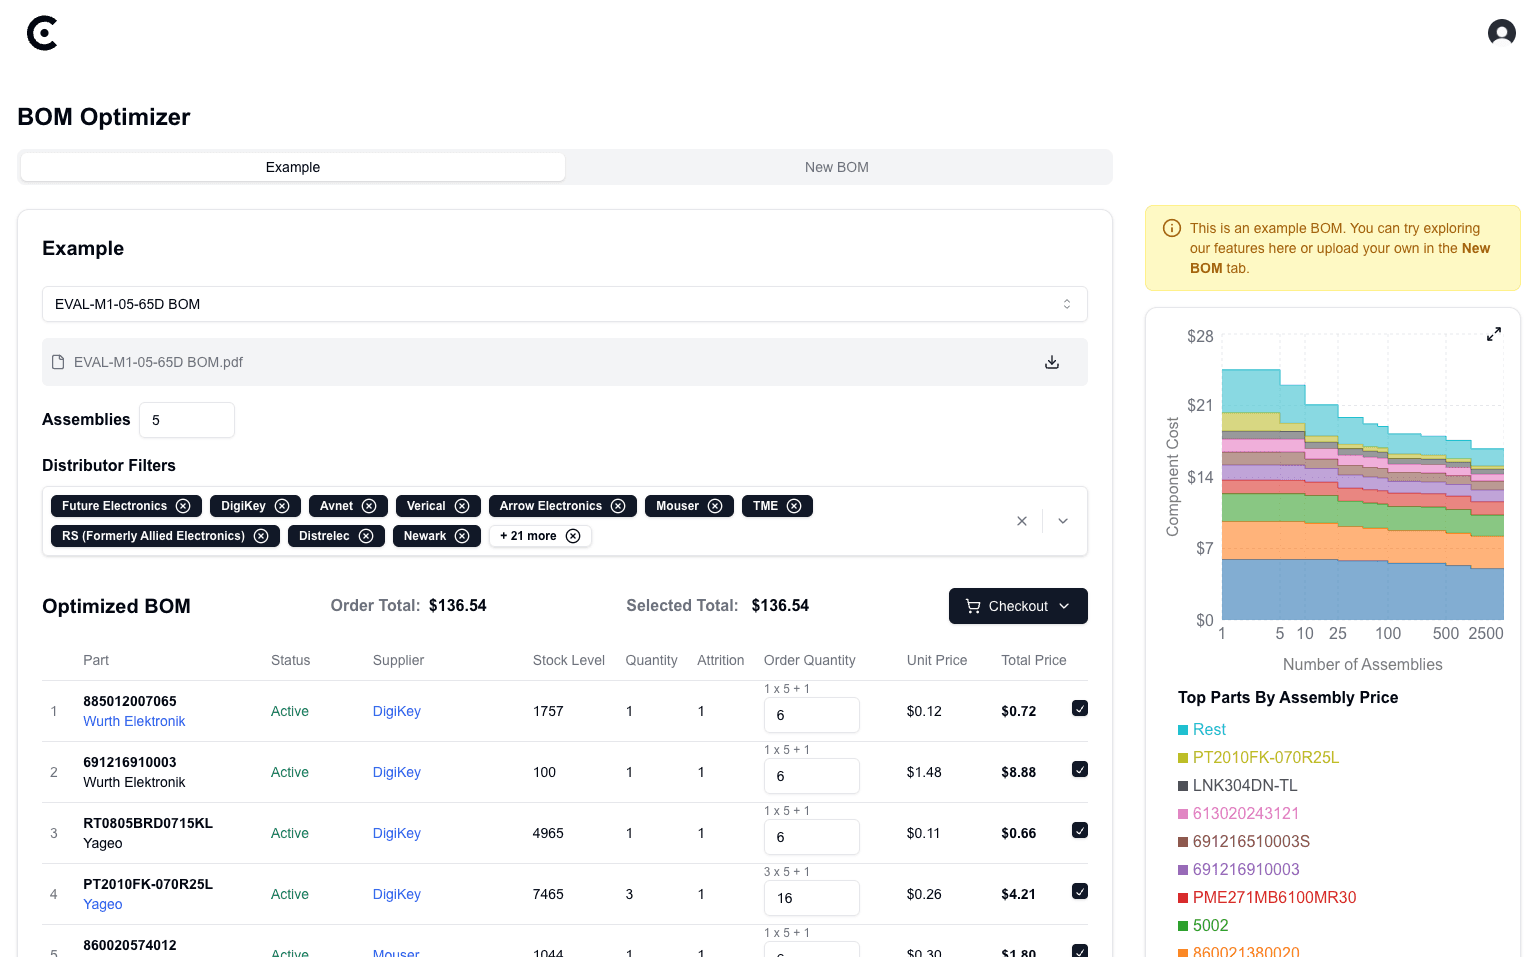
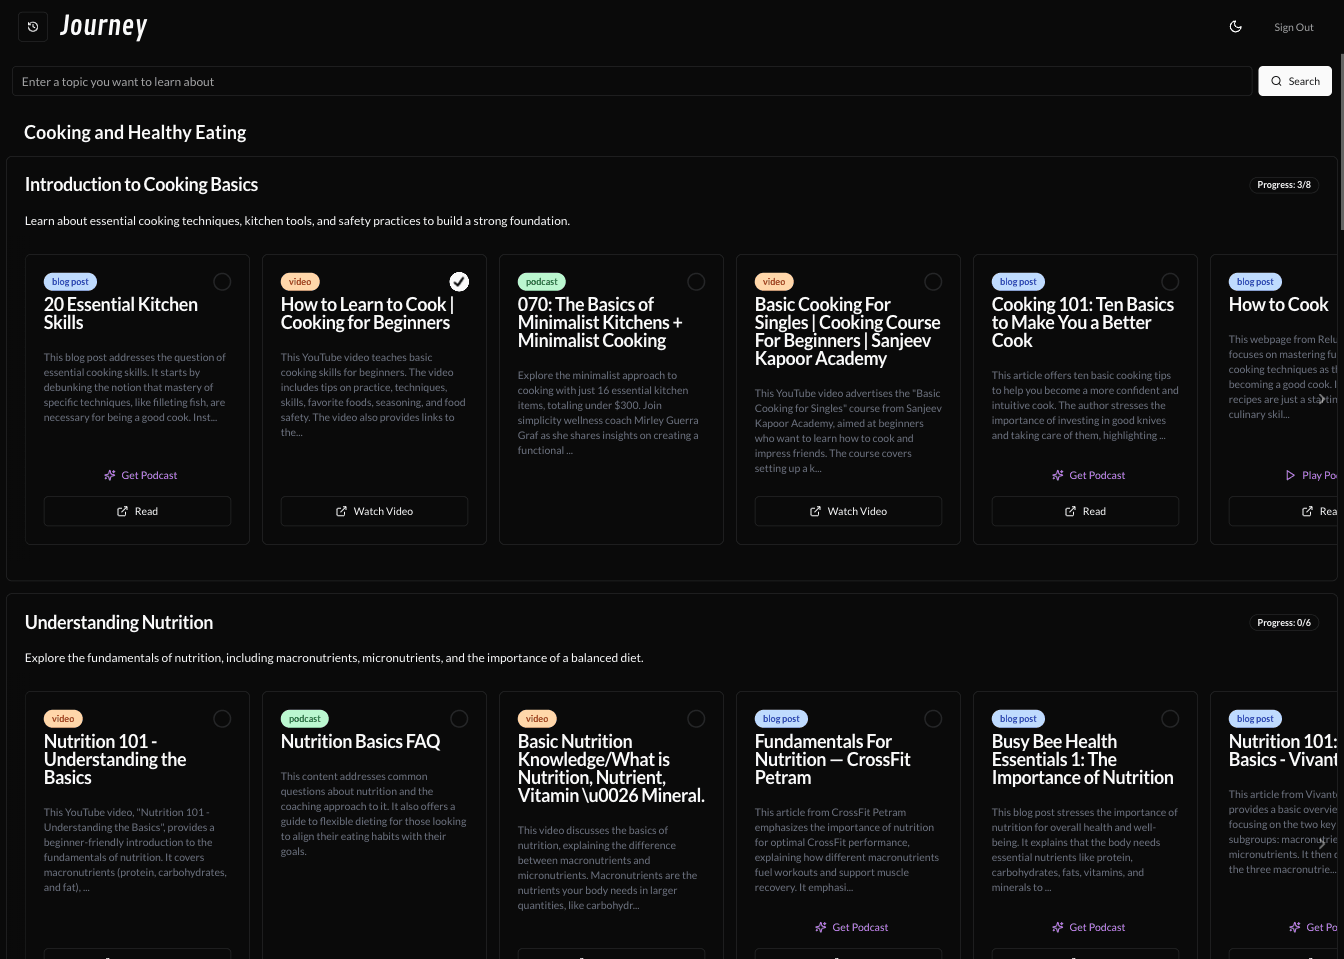
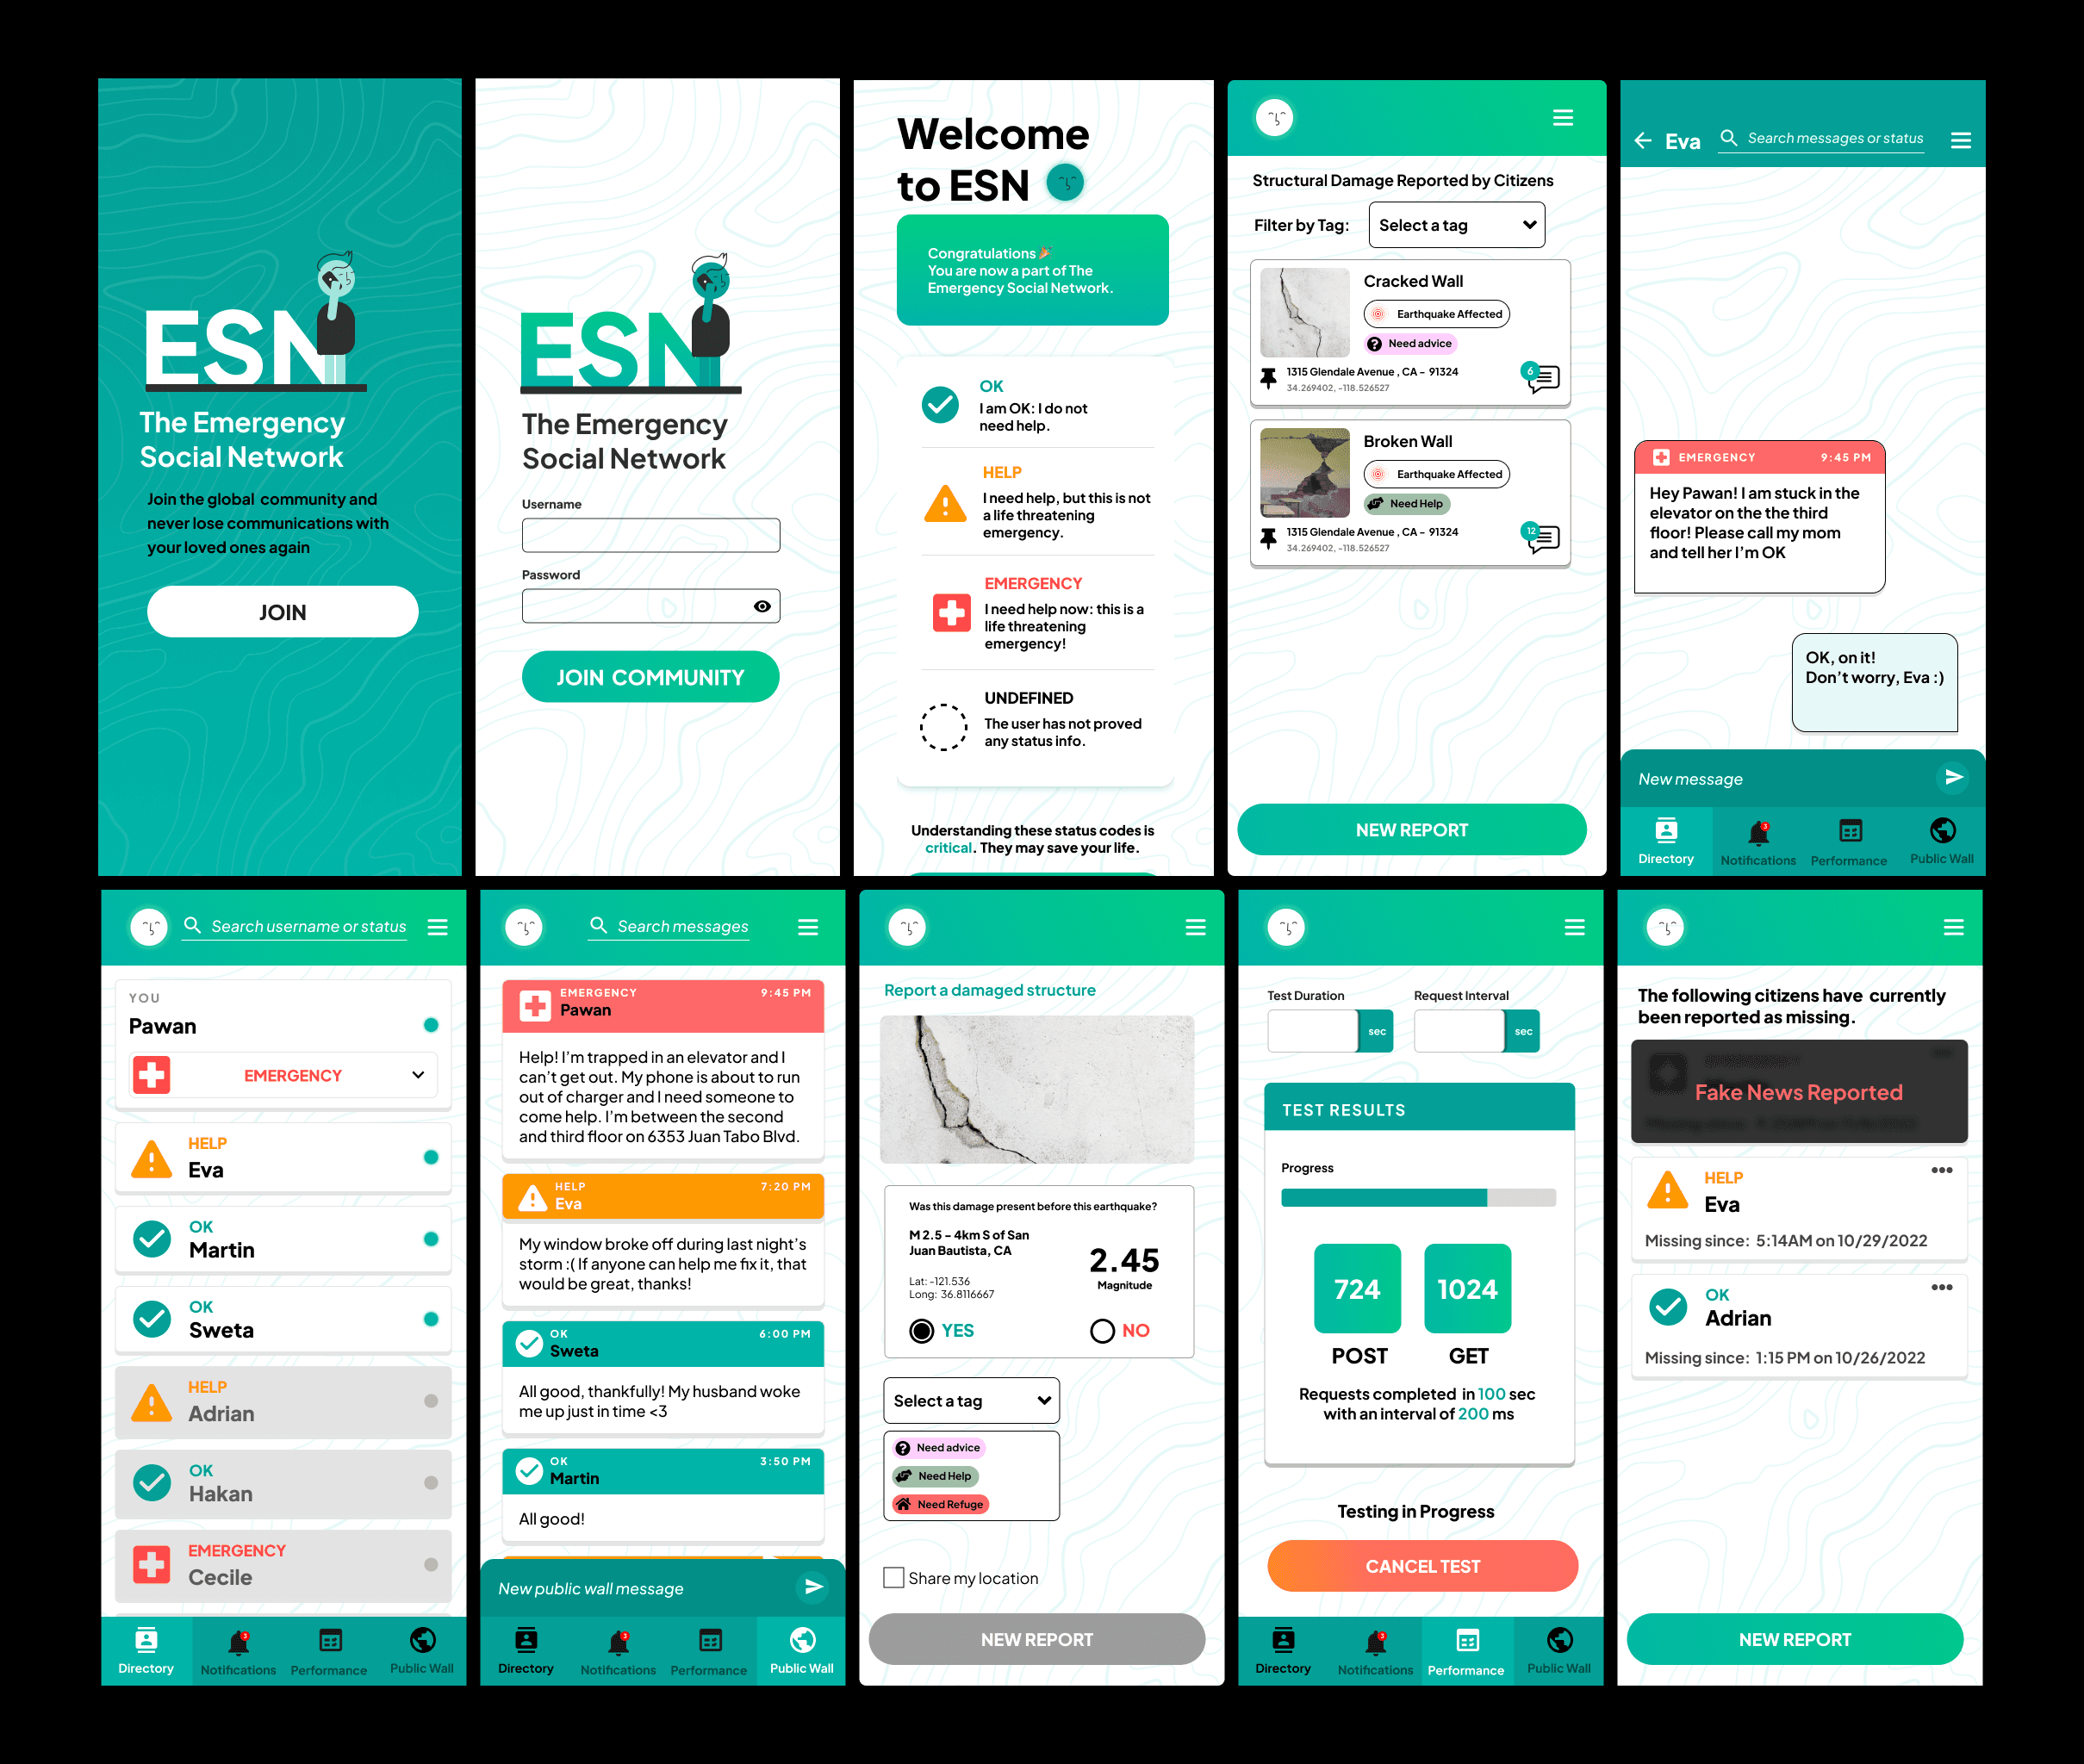
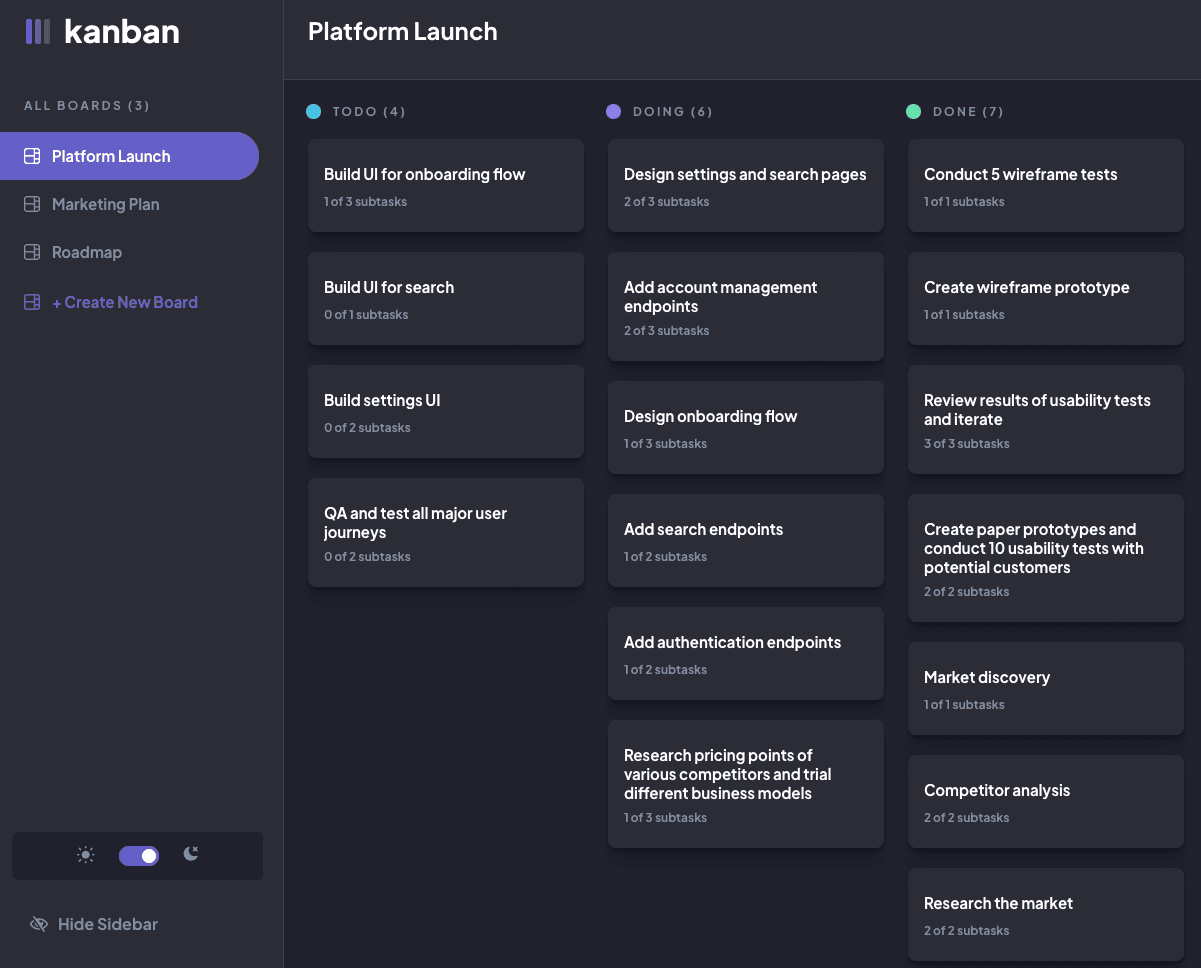
I’m Pawan, a full-stack engineer who cares as much about how a tool feels as about what it computes. For the past few years I’ve built the software frontier labs use to understand their models: at xAI, Nebula for model debugging and RL observability, and Starfleet for the human data behind Grok’s post-training; now at Thinking Machines Lab, a platform for runs, rollouts, datasets and evals.

Before that I was the founding engineer at Converge Lab, built real-time infrastructure at TuneIn, and spent two years shipping products in Fukuoka, Japan. I studied software engineering at Carnegie Mellon.

I like putting tools in people’s hands early and iterating with them. Designing interfaces has been a hobby for as long as I’ve been writing code, so I usually design what I build.

Education

  • Carnegie Mellon University

    2023

    M.S. Software Engineering

    Mountain View, CA · Graduate Teaching Assistant · Research Associate

  • Visvesvaraya Technological University

    2020

    B.E. Computer Science & Engineering

    Nitte, India · Sakura Science Fellow

Recognition

  • Sakura Science Fellow

    Japan Science and Technology Agency–funded research internship at Ritsumeikan University.

  • Graduate Teaching Assistant

    Foundations of Software Engineering; Software Requirements & Interaction Design; Introduction to Graduate Studies at Carnegie Mellon.

  • Student Leader

    ECE Graduate Organization, Carnegie Mellon, Fall 2022.

  • Youth Icon

    First place among 5,000 participants in a national public speaking competition, 2019.

(06)Selected work

Things I’ve shipped along the way.

Archive & experiments

(07)Toolkit

Languages & frameworks: Python, TypeScript, Go, SQL, React, FastAPI, Node.js, GraphQL, Next.js

AI & ML infrastructure: RL rollout analysis, LLM evaluation, Training-data tooling, MCP, Agent SDKs, RAG, LangChain

Data & infrastructure: ClickHouse, Spanner, BigQuery, PostgreSQL, Redis, Kafka, GCP, AWS, Kubernetes, Docker, Terraform

(08)WritingAll posts →

Notes from the workbench.

(09)Contact

Let’s talk.

Say hello about research tooling, interfaces for AI, or whatever you’re building.